
Legacy relational databases (like single-node PostgreSQL or MySQL) were engineered under an assumption that hardware would scale vertically inside a single data center. As modern digital enterprises expand globally, engineering teams encounter the hard physical ceiling of this paradigm: vertical compute limits, replication lag across read-replicas, single-writer bottlenecks, and high-risk database sharding logic written directly into application code.
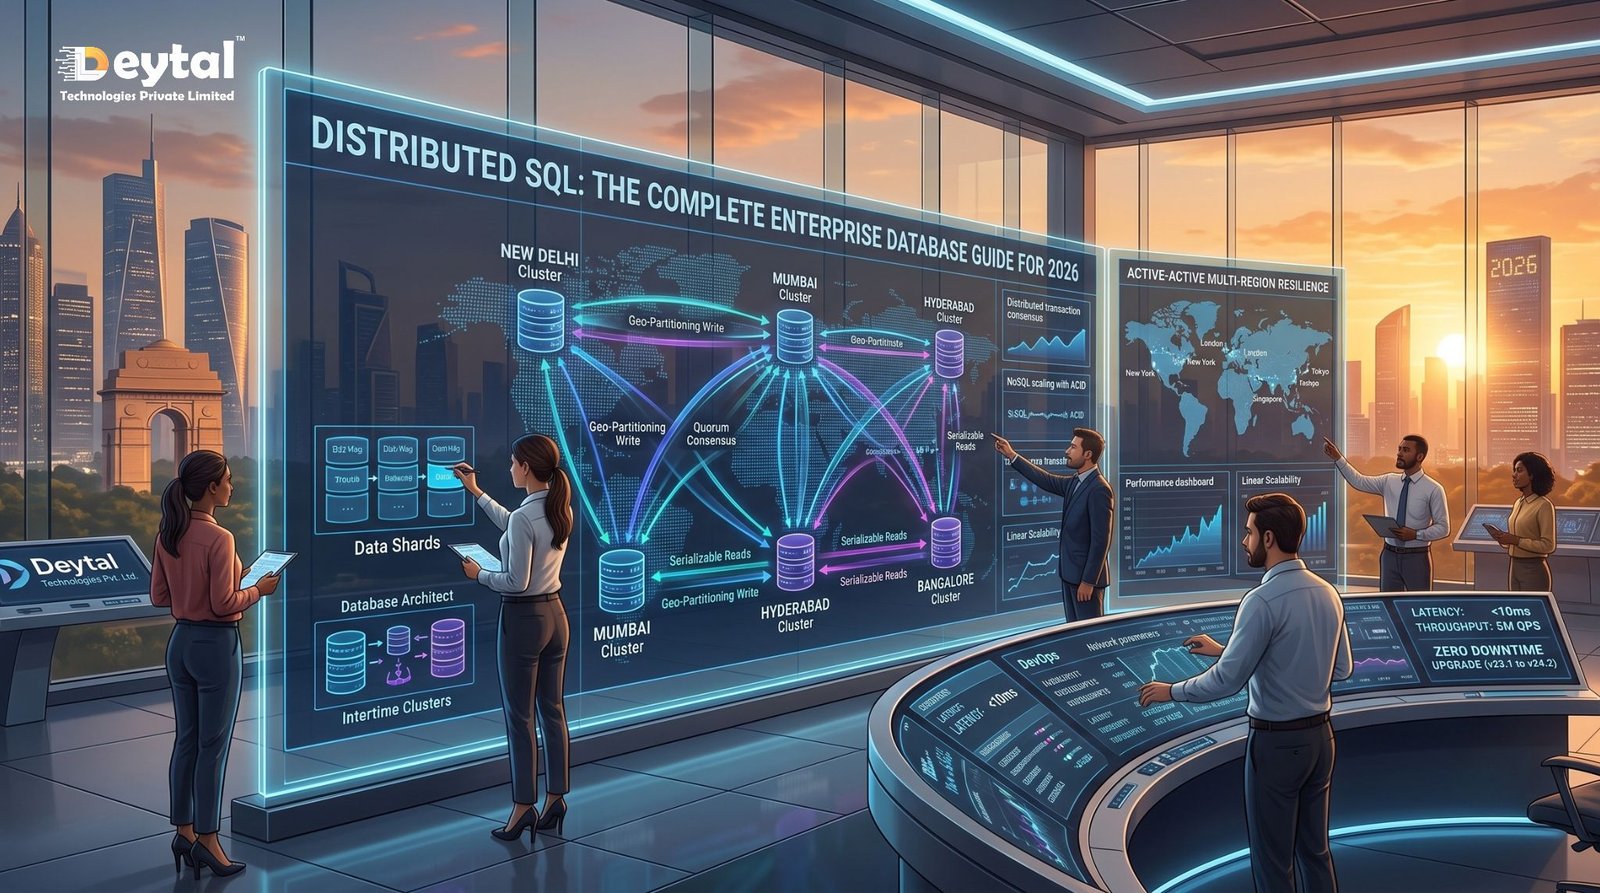
Distributed SQL Architecture (often termed NewSQL) rewrites database infrastructure for the cloud-native era. By pairing a familiar SQL relational interface and strict ACID transaction guarantees with the horizontal scalability and fault tolerance of NoSQL, modern engines—such as CockroachDB, YugabyteDB, and Google Cloud Spanner—enable multi-region active-active workloads with zero scheduled downtime.
The Operational Ceiling of Legacy Relational Databases
Relying on traditional monolithic RDBMS deployments at enterprise scale introduces significant engineering vulnerabilities:
- Fragile Manual Sharding: Dividing databases into regional or customer-based shards forces developers to manage shard routing within business logic, making cross-shard queries complex and error-prone.
- Asynchronous Replication Lag: Relying on primary-replica configurations creates “read-after-write” inconsistencies, where users read stale data moments after submitting an update.
- Single-Region Failure Vulnerability: When the primary write node crashes, failover mechanisms to standby instances take minutes, resulting in immediate application downtime and potential data loss.
- Complex Data Sovereignty Compliance: Complying with localized data regulations (like GDPR or India’s DPDP Act) is difficult when data models cannot pin rows to specific geographical regions at the storage layer.
Monolithic RDBMS vs. NoSQL vs. Distributed SQL
| Architecture Metric | Traditional RDBMS (PostgreSQL/MySQL) | Distributed NoSQL (Cassandra/MongoDB) | Distributed SQL (CockroachDB/Spanner) |
| Scalability Model | Vertical (Larger servers / Read replicas) | Horizontal (Shared-nothing clusters) | Horizontal (Elastic, dynamic rebalancing) |
| Transaction Consistency | Strict ACID (Single node only) | Eventual Consistency (BASE) | Distributed Strict ACID (Global Serializable) |
| Query Flexibility | Advanced joins, schemas, and SQL | Limited query flexibility, denormalized | Full relational SQL, complex joins, constraints |
| Disaster Recovery | Active-Passive (Manual/Failover lag) | Active-Active (Tolerates node drops) | Multi-Region Active-Active (Raft/Paxos consensus) |
| Application Overhead | High (Application manages custom sharding) | High (App manages data anomalies) | Zero (Database manages distribution natively) |
Engineering Pillars of a Modern Distributed SQL Platform
1. Consensus-Driven Storage Engines & Data Replication
Implement distributed consensus protocols (such as Raft or Paxos) to coordinate transactions across multi-node clusters. Developing fault-tolerant data ingestion layers and distributed microservices through Custom Software Development Services ensures consistent data writes across multi-region environments without manual sync locks.
2. High-Concurrency, Edge-Aware Web Applications
Harness localized read/write performance by directing global web traffic to the nearest geographic database replica. Deploying responsive user applications via Website Development Services prevents regional network latency spikes and ensures sub-second page interaction times.
3. Visual Cluster Monitoring & Observability UI
Managing multi-region database nodes across hybrid cloud providers requires clear operational transparency. Designing real-time cluster health monitors, range-distribution maps, and latency dashboards through UI/UX Design Services equips database administrators to spot replication lag instantly.
4. Real-Time Offline Sync & Resilient Mobile Backends
Deliver uninterrupted mobile workflows during intermittent network connectivity. Structuring conflict-free mobile APIs backed by distributed relational storage using Mobile App Development Services guarantees seamless background data synchronization across iOS and Android clients.
5. Distributed Content Architecture & Technical SEO Protection
Protect public-facing catalogs and content engines from downtime during peak traffic events. Pairing decoupled WordPress Development Services with advanced SEO Services maintains top organic search authority, fast indexing, and optimal Core Web Vitals scores.
6. Automated Data Pipelines & High-Converting Campaign Funnels
Leverage real-time transactional data across distributed clusters to trigger dynamic personalization funnels, continuously monitored and scaled through Digital Marketing Services.
Modernize Your Database Architecture with Deytal Technologies
Migrating mission-critical enterprise workloads from legacy monoliths to a distributed SQL cluster requires rigorous schema refactoring, consensus tuning, and zero-downtime cutover planning. Deytal Technologies Pvt. Ltd. designs and executes distributed database modernizations, enterprise software architectures, and resilient cloud systems built to support continuous business growth.
Frequently Asked Questions (FAQ)
Q1: How does a distributed SQL database ensure ACID compliance across multiple servers?
Distributed SQL systems use consensus algorithms (like Raft or Paxos) alongside Hybrid Logical Clocks (HLC) or synchronized atomic hardware clocks (like Google TrueTime). Writes require a quorum of distributed nodes to commit, ensuring strict serializability without split-brain anomalies.
Q2: Is distributed SQL faster than a traditional single-node database?
For simple single-region write operations, a local monolithic database often has lower baseline latency because it avoids cross-network consensus handshakes. However, for massive write volumes, large data footprints, and global multi-region deployments, distributed SQL provides far higher total throughput, automated horizontal scaling, and eliminates single-node resource saturation.
Q3: How does geo-partitioning work in distributed SQL engines?
Geo-partitioning allows administrators to define database rules that map specific rows, partitions, or tables to storage nodes located within designated geographical borders. This keeps read/write latency low for local users and directly solves regulatory data residency mandates.
